A free security tracker for practitioners
Cybersecurity Tracker aggregates security news and vulnerability intelligence into one ranked, filterable feed. It runs autonomously, costs nothing, and asks for no account.
Built and operated by Gary Bowen
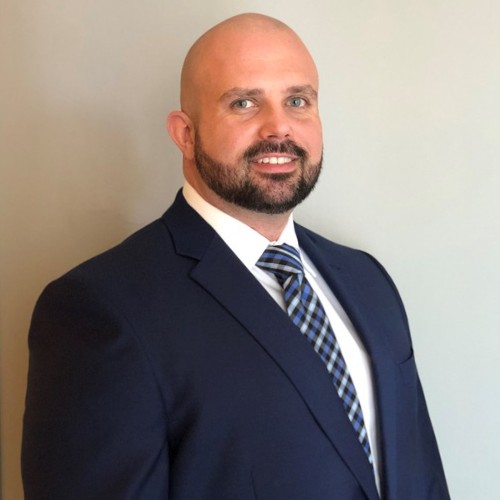
I am a cybersecurity leader, and I built Cybersecurity Tracker to solve a problem I have on my own team: too many sources, too little time, and no free tool that ranks what actually matters. It runs autonomously and stays free because the security community it serves should not have to pay to keep up.
Feedback makes it better. You can connect with me on LinkedIn or send feedback directly.
Send feedback
A bug, a source we should add, or anything else. No account needed. Leave contact details only if you want a reply.
How it works
Reporting is aggregated from multiple sources. Anything Cybersecurity Tracker computes or infers is labelled as its own judgment, never as a claim made by a source. The pipeline combines security reporting, vulnerability intelligence, public records, and other structured data. Stories are de-duplicated and clustered across outlets, classified by category, and summarized in our own words; vulnerabilities are enriched and ranked into priority tiers. Leak-site claims are always labeled unverified. Licence-required credits remain on theattributions page.
Editorial policy
- Summaries are two to three sentences in our own words. We never reproduce article text beyond a short phrase.
- Every item links to and names its sources.
- Leak-site entries are always labeled "Unverified claim. Claimed by [group]." We do not present a claim as a confirmed breach.
- We respect robots.txt on any page fetch and use the syndicated feed when full text is disallowed.
How priority works
| Tier | What it means | What to do this week |
|---|---|---|
| Track | No signal currently raises the record above the baseline tier. | Review during routine vulnerability management. |
| Track* | A public exploit, elevated exploitation probability, or Stakeholder-Specific Vulnerability Categorization (SSVC) verdict raises this record for closer watching. | Watch for exploitation and prepare the likely fix. |
| Attend | The SSVC-style verdict calls for attention, but no confirmed exploitation signal sets an Act floor. | Plan remediation this week and confirm ownership. |
| Act | Confirmed active exploitation or an SSVC-style Act verdict requires prompt action. | Prioritize remediation now and verify compensating controls. |
| Act now | Ransomware association sets the top tier; active exploitation can also rise one tier through the end-of-life or open-exposure modifier. | Respond now and verify containment, remediation, and exposure. |
Known Exploited Vulnerabilities (KEV) catalogs provide confirmed-exploitation evidence.
A KEV-listed or confirmed-exploited item is never below Act.
What each input can change
| Input | Source | Can do | Cannot do | When absent |
|---|---|---|---|---|
| Confirmed exploitation | Cybersecurity and Infrastructure Security Agency (CISA), VulnCheck, or European Union Agency for Cybersecurity (ENISA) catalog membership, or a CISA Vulnrichment active-exploitation judgment | Set an Act floor. | Cannot lower a stronger result. | No confirmed-exploitation floor is applied. |
| Ransomware association | Tracked exploitation catalog evidence | Set Act now. | Cannot be inferred from news volume or product exposure. | No ransomware floor is applied. |
| Stakeholder-Specific Vulnerability Categorization (SSVC) verdict | CISA Vulnrichment judgments, with CVSS-derived fallbacks where a judgment is absent | Set Track, Track*, Attend, or Act. | Cannot lower an exploitation floor or set Act now by itself. | An indeterminate input remains indeterminate, never zero. |
| Public exploit | Exploit references and maturity recorded by the tracker | Set a Track* floor. | Cannot reach Attend or Act by itself. | No public-exploit floor is applied. |
| Exploit Prediction Scoring System (EPSS) | Exploit Prediction Scoring System score and percentile | Set a Track* floor at the configured threshold and affect order within a tier. | Cannot reach Attend, Act, or Act now by itself. | No EPSS tier or rank term is applied. |
| End of life | The tracker product lifecycle crosswalk | Lift an actively exploited item by at most one tier. | Cannot move a tier without active exploitation or ransomware association. | No lifecycle escalation is applied. |
| Product exposure | Common Vulnerability Scoring System (CVSS) vector and the tracker product-class crosswalk | Lift an actively exploited or ransomware-associated item by at most one tier when exposure is open. | Cannot move a tier when exposure is controlled, small, or not paired with exploitation. | Exposure is shown as unknown and no exposure escalation is applied. |
| Within-tier signals | Common Vulnerability Scoring System (CVSS), Common Weakness Enumeration (CWE), technical impact, privileges, due proximity, news, exploit maturity, threat Internet Protocol (IP) addresses, and observed instances | Order records within the tier. | Cannot move a record to another tier. | Each absent signal contributes nothing and is never rendered as zero. |
A vulnerability's priority is a tier, not a raw sum. Confirmed exploitation sets an Act floor, ransomware association sets Act now, and an actively exploited item can rise one step when the affected product has an end-of-life version. A Stakeholder-Specific Vulnerability Categorization (SSVC) style decision can set Track through Act; a public exploit or elevated Exploit Prediction Scoring System (EPSS) result can set Track*. Product exposure raises a tier only when an internet-facing product is already under active exploitation or ransomware use, and then by one step at most. The rank within a tier draws on the listed within-tier signals. It is a triage signal, not a substitute for your own risk assessment.
Five further measures separate items that sit in the same tier. The first is how far the flaw reaches: whether exploiting the affected component lets an attacker reach resources beyond that component's own security authority. The second is Privileges Required, which records whether an attacker needs no account, an ordinary account, or an administrative one. Both only ever add to an item's score, never subtract, so they can change the order of items inside a tier. Neither can move an item into a different tier, and neither is treated as evidence of exploitation.
We read reach beyond the affected component from whichever measure the record's version of the standard provides. Version 3 states it as Scope, a single changed or unchanged value. Version 4 removed Scope and replaced it with three measures of the impact on a system beyond the vulnerable one, so we read those instead. We do not read version 4's Scope letter, because that version reuses it for an unrelated safety measure describing physical harm to a person, and reading it as Scope would state something the record does not say.
The two versions earn the same amount. Version 4 grades how large the further impact is, where version 3 records only whether it happened, and scoring the grade would rank two items differently for the same real-world property purely because of which version of the standard their record happens to use. Privileges Required means the same thing in versions 3 and 4, so we read it from both.
The priority number you see is rounded for reading, to one decimal place. Two items can show the same rounded number and still sit in a fixed order, because we rank them on the unrounded value. That ordering is stable and repeatable, not arbitrary. The decimal preserves more of the underlying score for reading, but it does not guarantee a unique displayed value. It is not a claim of precision about risk, and a difference of a few tenths of a point is not a meaningful difference in urgency. The breakdown under each item always adds up to the sub-score printed beneath it, and the rounded figure we show alongside can differ from the unrounded one we rank by, by less than one tenth of a point.
We list an entry for reach and Privileges Required only when the measure raises the score. A record whose flaw stays inside the affected component, or where an attacker needs administrative privileges, shows no entry, and neither does a record where we cannot read the measure at all. An absent entry never means we assumed a zero, and it is not a claim that anything was measured. The same rule governs the two measures described next.
A third measure is the weakness class: what an attacker actually gets. The Common Weakness Enumeration (CWE) identifier on a record tells us whether the flaw lets an attacker run code of their choosing, defeat an access control, or read information they should not see. The severity score already says how bad the outcome is, and this says what kind of outcome it is, which severity alone does not carry. We weigh only the classes listed in an operator reviewed table we maintain, and a class that is not on that table earns nothing. That is a refusal to make a claim, not a finding that the weakness is harmless. Where an item does earn one, the breakdown under it names the class in plain words, so what we counted is visible on the item itself.
A fourth is how mature the public exploit is. Where a catalogue records a working exploit for an item, it also records a grade: the Metasploit project rates how reliably its module works, and the VulnCheck exploit database records what the exploit gives an attacker. We use that grade, so among items that are otherwise equal, the one with a more reliable or more powerful public exploit ranks higher. It is a small amount, and a difference in exploitation likelihood or severity between two items will usually outweigh it. This is not a second opinion about whether an item is exploited. It reads the same two sources we use to decide how exploited an item is, it is capped far below the distance between any two steps of that judgment, and it cannot move an item into a different tier. It applies only where a catalogue provides a grade. Where a catalogue lists many exploits for one item we store the first several rather than all of them, so we grade the best of the ones we hold, which is not always the best that exists.
A fifth is direction of travel. Every other measure describes where an item stands today, and this one describes where it is heading. We keep a daily archive of Exploit Prediction Scoring System readings, and we compare an item's most recent reading against its oldest reading in the last thirty days. An item whose predicted likelihood climbed from almost nothing to near certain in a month is a different situation from one that has sat at the same high number all along, even though the current number alone cannot tell them apart. Only a rise counts. A fall earns no penalty, because the likelihood measure itself has already fallen with it, and subtracting again would count one decline twice. It is capped well below the likelihood measure itself, so where an item stands always outweighs how fast it moved, and it cannot move an item into a different tier. It applies to a small minority of items on any given day, and which items those are changes as the readings do.
We make no claim about direction of travel unless we can measure it. An item we have not tracked long enough, or whose rise is too small to print, shows no entry at all, which is not a reading of no change. If the archive stops updating we withhold the measure from every item rather than describe a month old move as current, and if an unusually large share of the whole archive moves on a single day, we withhold the measure until that day has passed out of the window: a shift on that scale is not about any one item, and a rise measured across it would not mean what a rise normally means. We do not say what caused it. The published readings could have been rebuilt, or a day's snapshot could have been written only in part, and the measurement cannot tell those apart. One limit worth stating: the comparison spans the readings we hold inside those thirty days, so a recently published item can rest on considerably fewer.
Threat intelligence tags contributed by the abuse.ch ThreatFox community are shown on an item with the date each indicator was first seen, and they do not change its priority. The tags are community submissions, and we hold a number a defender acts on to the same evidence standard as our other sources.
What it costs
Nothing, to you. No account, no paywall, no ad tracking. Anonymous, cookie-free Cloudflare Web Analytics measures aggregate site use. See the attributions and licences page for how every source is credited, and the API if you want the raw data.
How often each thing refreshes
Every command this tracker runs, with where it runs and how often. 46 run on a schedule and 42 are run by hand, so a number that has not moved is not necessarily a number that is stuck.
| Command | Runs | Cadence | Last successful run | Failure behavior |
|---|---|---|---|---|
| argus-ops-summary | CST-DigestWeekly | Mondays 07:30, a step of digest-weekly | A failure is recorded and retries on the next scheduled pass. | |
| audit-artifacts | CST-Healthcheck | daily | A failure is recorded and retries on the next scheduled pass. | |
| backfill-cisa-ssvc | CST-Structured | daily family watermark, 500 rows per sweep | A failure is recorded and retries on the next scheduled pass. | |
| backup | CST-Backup | daily 02:00 | A failure is recorded and retries on the next scheduled pass. | |
| check-job-liveness | CST-Jobs | daily schedule with a 23-hour family watermark | No successful run recorded | A failure is recorded and retries on the next scheduled pass. |
| cloudflare-usage | CST-Healthcheck | daily 08:00, after artifact audit and before checks/alert delivery | A failure is recorded and retries on the next scheduled pass. | |
| dependency-audit | CST-Healthcheck | daily 08:00, after artifact audit and before checks/alert delivery | A failure is recorded and retries on the next scheduled pass. | |
| deploy | CST-Structured | after news and after structured (also manual news runs); export runs inside it | A failure is recorded and retries on the next scheduled pass. | |
| digest-daily | CST-DigestDaily | daily 07:00; Monday subscriber delivery is deferred to the combined 07:30 weekly step | A failure is recorded and retries on the next scheduled pass. | |
| digest-weekly | CST-DigestWeekly | Mondays 07:30; sole Monday subscriber delivery combines the seven-day recap and the window since Sunday 07:00 ET | A failure is recorded and retries on the next scheduled pass. | |
| enrich-threatfox | CST-Structured | every run | A failure is recorded and retries on the next scheduled pass. | |
| enrich-vulns | CST-Structured | twice per combined run (also manual news runs) | A failure is recorded and retries on the next scheduled pass. | |
| fetch-actor-aliases | CST-Structured | weekly family watermark | A failure is recorded and retries on the next scheduled pass. | |
| fetch-atomic | CST-Structured | 8-hour family watermark | A failure is recorded and retries on the next scheduled pass. | |
| fetch-attack | CST-Structured | 24-hour family watermark | A failure is recorded and retries on the next scheduled pass. | |
| fetch-cisa-advisories | CST-Structured | 8-hour family watermark | A failure is recorded and retries on the next scheduled pass. | |
| fetch-cloud-vulns | CST-Structured | 8-hour family watermark | A failure is recorded and retries on the next scheduled pass. | |
| fetch-cvelist | CST-Structured | 8-hour family watermark | A failure is recorded and retries on the next scheduled pass. | |
| fetch-etda-actors | CST-Structured | weekly family watermark | A failure is recorded and retries on the next scheduled pass. | |
| fetch-greenbone-scanner-detections | CST-Structured | weekly family watermark | No successful run recorded | A failure is recorded and retries on the next scheduled pass. |
| fetch-hibp | CST-Structured | 8-hour family watermark | A failure is recorded and retries on the next scheduled pass. | |
| fetch-ics-advisories | CST-Structured | 8-hour family watermark | A failure is recorded and retries on the next scheduled pass. | |
| fetch-jobs | CST-Jobs | 12-hour schedule with an 11-hour family watermark | A failure is recorded and retries on the next scheduled pass. | |
| fetch-leak-delistings | CST-Structured | weekly family watermark | A failure is recorded and retries on the next scheduled pass. | |
| fetch-lifecycle | CST-Structured | 8-hour family watermark | A failure is recorded and retries on the next scheduled pass. | |
| fetch-malicious-packages | CST-Structured | 8-hour family watermark | A failure is recorded and retries on the next scheduled pass. | |
| fetch-malpedia-references | CST-Structured | weekly family watermark | A failure is recorded and retries on the next scheduled pass. | |
| fetch-malware-families | CST-Structured | weekly family watermark | A failure is recorded and retries on the next scheduled pass. | |
| fetch-metasploit | CST-Structured | 8-hour family watermark | A failure is recorded and retries on the next scheduled pass. | |
| fetch-nuclei-scanner-detections | CST-Structured | weekly family watermark | A failure is recorded and retries on the next scheduled pass. | |
| fetch-ransomware-live | CST-Structured | 8-hour family watermark | A failure is recorded and retries on the next scheduled pass. | |
| fetch-shodan | CST-Structured | weekly family watermark | A failure is recorded and retries on the next scheduled pass. | |
| fetch-sigma | CST-Structured | 8-hour family watermark | A failure is recorded and retries on the next scheduled pass. | |
| fetch-takedowns | CST-Structured | 8-hour family watermark; OFAC subfeed weekly guarded | A failure is recorded and retries on the next scheduled pass. | |
| fetch-threatfox | CST-Structured | weekly family watermark | A failure is recorded and retries on the next scheduled pass. | |
| fetch-ubuntu-patches | CST-Structured | 24-hour family watermark | A failure is recorded and retries on the next scheduled pass. | |
| fetch-vendor-patches | CST-Structured | 8-hour family watermark | A failure is recorded and retries on the next scheduled pass. | |
| healthcheck | CST-Healthcheck | daily 08:00 | A failure is recorded and retries on the next scheduled pass. | |
| jobs | CST-Jobs | every 12 hours; own data/jobs.lock, never the pipeline lock, and no deploy step -- postings publish on the next structured deploy | No successful run recorded | A failure is recorded and retries on the next scheduled pass. |
| jobs-quality-report | CST-Jobs | correction-rate adaptive cadence guard: daily, every other day, then weekly; deterministic and zero model calls | A hard error or interrupted run does not advance the guard and retries on the next scheduled pass. A warning holds the active guard for at most 23 hours before retry. | |
| monitor-heartbeat | CST-Healthcheck | daily after checks and alert delivery | A failure is recorded and retries on the next scheduled pass. | |
| news | CST-Structured | every 3 hours (live trigger and the checked-in CST-Structured.xml both PT3H, re-measured 2026-09-07), news-first; manual news-only front door | A failure is recorded and retries on the next scheduled pass. | |
| send-job-alerts | CST-DigestDaily | daily 07:00, after reply/NDR and delivery reconciliation | A failure is recorded and retries on the next scheduled pass. | |
| snapshot-publish | CST-Structured | once after the combined run (also manual news runs and the CST-Backup floor); snapshot + publish, warn-not-fail | A failure is recorded and retries on the next scheduled pass. | |
| structured | CST-Structured | every 3 hours (live trigger and the checked-in CST-Structured.xml both PT3H, re-measured 2026-09-07); safe pull, then environment rebuild, then news-first | A failure is recorded and retries on the next scheduled pass. | |
| summarize-edgar | CST-Structured | daily family watermark, full coverage bounded by llm.max_daily_usd (edgar.summary_max_per_day is an optional throttle, off by default) | A failure is recorded and retries on the next scheduled pass. | |
| backfill-cvss | By hand | converged backlog; fetch-nvd enriches in-run | Run by hand. A failure is recorded; no scheduled retry is promised. | |
| backfill-cwe | By hand | converged backlog; fetch-nvd enriches in-run | Run by hand. A failure is recorded; no scheduled retry is promised. | |
| backfill-edgar-sic | By hand | gap repair; fetch-edgar fills live | Run by hand. A failure is recorded; no scheduled retry is promised. | |
| backfill-epss-history | By hand | historical archive backfill, CONVERGED 2026-07-17; the daily top-up is the fetch-epss step of every CST-Structured run | Run by hand. A failure is recorded; no scheduled retry is promised. | |
| backfill-missing | By hand | force-fill repair sweep | Run by hand. A failure is recorded; no scheduled retry is promised. | |
| backfill-msrc | By hand | window fill; fetch-msrc runs in-run | Run by hand. A failure is recorded; no scheduled retry is promised. | |
| backfill-poc | By hand | bounded one-shot pass | Run by hand. A failure is recorded; no scheduled retry is promised. | |
| backfill-published | By hand | converged one-shot | Run by hand. A failure is recorded; no scheduled retry is promised. | |
| backfill-ransomlook | By hand | historical claim pull | Run by hand. A failure is recorded; no scheduled retry is promised. | |
| backfill-relevance-window | By hand | REC-390 finite strategic fill; per-source checkpoints resume interruptions, while daily health reports open strategic debt or a completed-backfill policy mismatch | No successful run recorded | Run by hand. A failure is recorded; no scheduled retry is promised. |
| backfill-sectors | By hand | cascade re-run; resolve-sectors runs in-run | Run by hand. A failure is recorded; no scheduled retry is promised. | |
| backfill-vendor-product | By hand | converged one-shot | Run by hand. A failure is recorded; no scheduled retry is promised. | |
| backfill-vendors | By hand | converged one-shot | Run by hand. A failure is recorded; no scheduled retry is promised. | |
| backfill-why | By hand | gap repair; why_it_matters fills in-run | Run by hand. A failure is recorded; no scheduled retry is promised. | |
| breach-coverage | By hand | read-only per-source enrichment coverage diagnostic (K4); informs the model-scale enrichment decision, writes nothing | No successful run recorded | Run by hand. A failure is recorded; no scheduled retry is promised. |
| classify-eval | By hand | classifier evaluation harness | Run by hand. A failure is recorded; no scheduled retry is promised. | |
| cost-report | By hand | spend reporting | No successful run recorded | Run by hand. A failure is recorded; no scheduled retry is promised. |
| diagnose-hhs-ocr | By hand | read-only portal diagnostic | No successful run recorded | Run by hand. A failure is recorded; no scheduled retry is promised. |
| export | By hand | front door; export_all runs inside every deploy step of CST-Structured and manual news runs | Run by hand. A failure is recorded; no scheduled retry is promised. | |
| fetch-gov-breaches | By hand | front door; fetch-hhs-ocr, fetch-ca-ag, and fetch-maine-ag run every CST-Structured pass | No successful run recorded | Run by hand. A failure is recorded; no scheduled retry is promised. |
| fetch-greynoise | By hand | INERT: greynoise.enabled false, key pending by email; wire on enablement | No successful run recorded | Run by hand. A failure is recorded; no scheduled retry is promised. |
| fetch-shadowserver | By hand | INERT: shadowserver.enabled false, key pending by email; wire on enablement | No successful run recorded | Run by hand. A failure is recorded; no scheduled retry is promised. |
| init-db | By hand | one-shot bootstrap | No successful run recorded | Run by hand. A failure is recorded; no scheduled retry is promised. |
| jobs-shadow-report | By hand | operator review front door for the exact four redacted shadow artifacts | No successful run recorded | Run by hand. A failure is recorded; no scheduled retry is promised. |
| normalize-dates | By hand | converged one-shot migration | Run by hand. A failure is recorded; no scheduled retry is promised. | |
| propose-attack | By hand | curation proposal; approved pairs land in committed YAML | No successful run recorded | Run by hand. A failure is recorded; no scheduled retry is promised. |
| propose-etda-actors | By hand | curation proposal; approved pairs land in etda_actor_names.yaml | No successful run recorded | Run by hand. A failure is recorded; no scheduled retry is promised. |
| publish-replica | By hand | front door; publish runs inside the snapshot-publish step | Run by hand. A failure is recorded; no scheduled retry is promised. | |
| reclassify-jobs | By hand | runs only after a reviewed classifier, parser, or taxonomy rule delta ships | No successful run recorded | Run by hand. A failure is recorded; no scheduled retry is promised. |
| recluster | By hand | budgeted re-adjudication on demand | Run by hand. A failure is recorded; no scheduled retry is promised. | |
| repair-active-since | By hand | FX5 one-shot, done | Run by hand. A failure is recorded; no scheduled retry is promised. | |
| repair-breaches | By hand | operator repair tool | Run by hand. A failure is recorded; no scheduled retry is promised. | |
| repair-flagged | By hand | operator repair tool (model pass) | Run by hand. A failure is recorded; no scheduled retry is promised. | |
| repair-ransomware-claims | By hand | bounded proven-duplicate repair plus candidate report; dry-run by default and intentionally operator-invoked because production data is operator-owned | Run by hand. A failure is recorded; no scheduled retry is promised. | |
| repair-score-sources | By hand | idempotent legacy relabel, done | Run by hand. A failure is recorded; no scheduled retry is promised. | |
| repair-titles | By hand | operator repair tool | Run by hand. A failure is recorded; no scheduled retry is promised. | |
| restore-replica | By hand | session bootstrap; the session-start hook runs it to pull the real corpus down, and it degrades honestly when GitHub is unreachable | No successful run recorded | Run by hand. A failure is recorded; no scheduled retry is promised. |
| scan-summaries | By hand | operator repair tool (model pass) | Run by hand. A failure is recorded; no scheduled retry is promised. | |
| snapshot | By hand | front door; the replica is produced by the final snapshot-publish step of CST-Structured, manual news runs, and CST-Backup | Run by hand. A failure is recorded; no scheduled retry is promised. | |
| verify-sources | By hand | operator preflight and source-diagnosis tool (Gary, 2026-07-17); healthcheck covers runtime health on cadence | Run by hand. A failure is recorded; no scheduled retry is promised. | |
| verify-turnstile-deploy | By hand | explicit non-production deployment verification; creates and deletes a disposable test-key Worker, so external and secret-bearing state must never enter scheduled or pull-request runs | No successful run recorded | Run by hand. A failure is recorded; no scheduled retry is promised. |
| verify-unsubscribe | By hand | operator-controlled live seed-inbox proof; it deliberately creates disposable provider state and sends exactly two messages, so it must never run on a schedule or in CI | No successful run recorded | Run by hand. A failure is recorded; no scheduled retry is promised. |
Generated from COMMAND_CADENCE in pipeline/src/cli.py and GUARDED_STEP_HOURS in pipeline/src/cadence.py, the same map the scheduled tasks are checked against, so this table cannot drift from what actually runs.